Why take this course?
Key Areas Covered
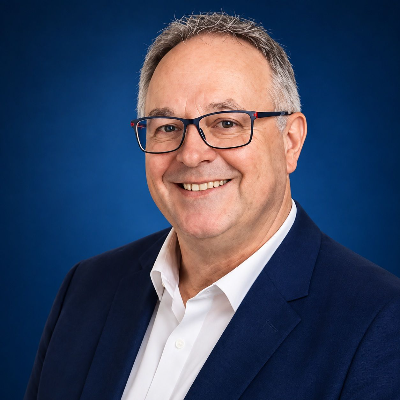
Milan Kučera
Milan Kučera is a senior validation and GxP technology professional focused on computerized systems, laboratory systems, data integrity, cloud environments, and emerging technologies in regulated organizations. His work combines practical validation and compliance expertise with a strong focus on risk-based approaches, quality strategy, and inspection readiness. He has a particular interest in the application of modern technologies, including cloud computing and AI, within regulated GxP environments, with emphasis on governance, data integrity, validation strategy, lifecycle management, and effective human oversight. His approach is to translate complex regulatory and technological expectations into practical controls, evidence, and implementation strategies that can be applied by Quality, IT, validation, and business teams.
Commonly Asked Questions About This Subject
What should happen when an AI system continues to meet overall performance targets but begins failing more often in one specific GMP scenario?
The localized deterioration should be investigated even if aggregate performance remains acceptable. Overall accuracy can conceal declining performance in the exact subset of cases that carries the greatest quality or operational risk.
This can occur when input characteristics change, a manufacturing process evolves, new product types are introduced, or the system encounters conditions that were poorly represented during its original evaluation. A dashboard showing stable average performance may therefore provide false reassurance.
The investigation should determine when the pattern began, which inputs or operating conditions are associated with it, and whether previous AI-supported decisions need review. The existing monitoring metric may also require refinement if it was unable to expose the problem early enough.
A predefined threshold remains useful, but crossing a threshold should not be the only reason to act. Repeated errors concentrated in a meaningful GMP scenario can justify escalation before the broader metric formally fails.
How should a company handle an AI system that technically passes validation but produces outputs that human reviewers frequently correct or reject?
Frequent correction or rejection is evidence that the validated performance may not represent actual operational performance. The pattern should be evaluated rather than treated as proof that human oversight is successfully controlling the system.
The first useful question is where disagreement occurs. If reviewers repeatedly intervene for the same product, data condition, decision type, or failure mode, the pattern may expose an intended-use limitation, inadequate acceptance criteria, changing input characteristics, or a weakness that was not adequately challenged during validation.
Override records become valuable lifecycle evidence in this situation. They can show whether performance remains suitable for the approved use and whether additional testing, tighter operating boundaries, model adjustment, or revalidation should be considered.
An inspection concern develops when extensive human correction is occurring but formal monitoring still reports satisfactory AI performance. The governance record should reflect how the system actually behaves in GMP operations, including the work humans perform to make its outputs acceptable.
When should a change to prompts, reference data, or surrounding infrastructure be treated as seriously as a model change?
A change deserves deeper assessment when it can materially alter the AI system's GMP-relevant output, regardless of whether the underlying model version changed. Focusing change control primarily on the model can miss significant behavioral changes introduced elsewhere in the operating environment.
A revised prompt can alter how information is interpreted or presented. Updated reference data can change the basis for recommendations. A modified interface can change what information reaches the model. Vendor or infrastructure changes can affect availability, processing, or system behavior.
The impact assessment should therefore start with potential effect on the approved use and expected performance. If the change can influence a critical output or decision, evidence may be needed to demonstrate that existing validation remains applicable.
This becomes difficult to defend when the change record says "no model change" and closes the assessment. Inspectors are likely to care about whether regulated behavior changed, not merely which technical component was modified.
What is the strongest evidence that human oversight of an AI-supported GMP process remains effective after months or years of routine use?
Evidence of meaningful intervention carries more weight than evidence that every required review was completed. Over time, familiarity with consistently acceptable AI outputs can turn an initially rigorous review into a predictable approval step.
Useful evidence includes rejected or corrected outputs, requests for additional information, escalations, documented disagreements, identified limitations, and cases where reviewers reached a different conclusion. Review patterns can also reveal warning signs such as rapidly shortening review times, near-universal acceptance, or substantial differences between reviewers performing the same task.
Low intervention rates are not automatically problematic. They do, however, deserve examination when the process depends on human oversight as a significant control.
Periodic review should therefore look beyond completion records and ask whether reviewers continue to detect meaningful problems when they occur. A procedure requiring human approval demonstrates that oversight was designed. Actual decision history provides stronger evidence that the oversight continues to function.
Your TalkFDA Webinar Experience
1. Confirmation
3. Join the Live Training
4. Watch Again Anytime
Testimonials
Ready to Strengthen Your Team? Let’s Build Your Training Plan.
Your team deserves the clarity.
Your organization deserves the confidence.
Upcoming Courses
Featured Courses